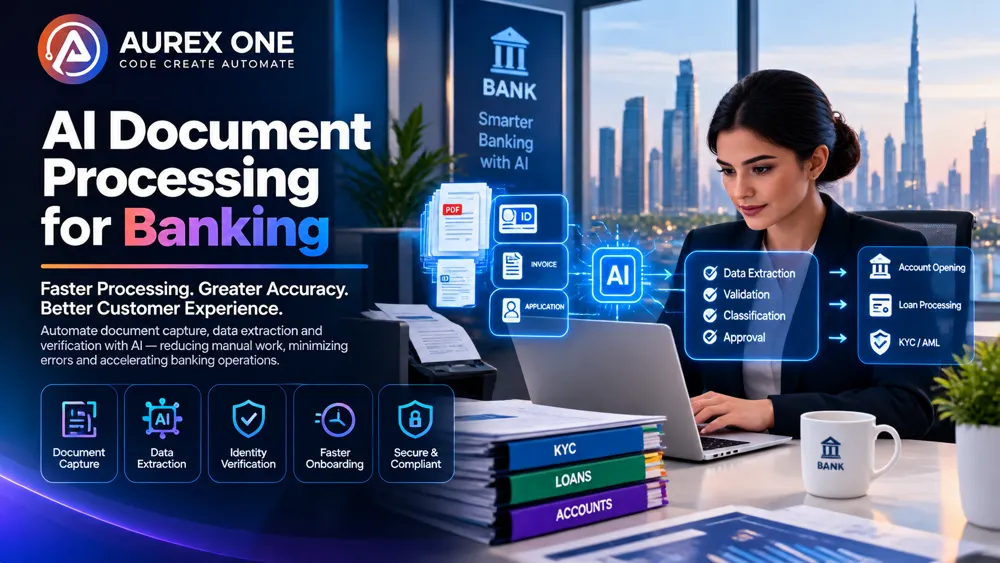
AI document processing banking can turn document-heavy onboarding and KYC work into a structured workflow where files are classified, information is extracted, values are validated, missing evidence is detected, and exceptions are routed to trained reviewers. Banks and fintech teams process identity documents, incorporation records, tax forms, proof of address, ownership information, statements, applications, and supporting evidence in many formats. AUREXONE AI TECHNOLOGIES builds document AI pipelines that combine extraction with rules, confidence thresholds, source evidence, human review, and integration into existing case-management systems.
This AI document processing banking guide focuses on the operational reality: document automation is not successful because OCR can read a page. It is successful when the institution can reliably move from an incoming file to verified structured data, preserve evidence, handle poor-quality inputs, detect inconsistencies, and know when a person must take over.
Why Banking Document Work Is Difficult to Automate
Documents vary by country, issuer, language, scan quality, layout, version, and customer type. A single onboarding case may contain native PDFs, phone photos, spreadsheets, screenshots, handwritten annotations, and scanned copies. Traditional templates work well when forms are stable but struggle when layouts change.
AI can improve flexibility by recognizing document types and extracting meaning rather than relying only on fixed coordinates. Yet flexibility introduces uncertainty. A production workflow therefore needs confidence scores, validation rules, source links, and exception handling. The system should make uncertainty visible instead of forcing a value into every field.
Step 1 | Intake, File Safety, and Case Association
The first challenge is knowing which files belong to which customer, entity, application, or review. The intake layer should validate file types, scan for malware, identify duplicates, preserve original files, and associate each document with the correct case.
Metadata collected at intake—channel, timestamp, uploader, application ID, document source, and declared type—can improve later validation. This is also the right point to reject unsupported formats or route encrypted and corrupted files for manual handling.
Step 2 | Document Classification
A classifier determines whether a file is a passport, national ID, utility bill, bank statement, certificate of incorporation, tax document, ownership chart, application form, or another required artifact. Classification can be hierarchical: first identify the broad family, then the specific subtype and jurisdiction.
For AI document processing banking for enterprise, the classifier should return confidence and alternatives. Low-confidence classifications can be shown to a reviewer or checked against expected document lists. The workflow should not silently interpret an unfamiliar file as the closest known category.
Step 3 | Banking Document Extraction
banking document extraction converts unstructured content into structured fields. Depending on the document, fields may include legal name, date of birth, address, company number, tax identifier, issue date, expiration date, signatories, beneficial owners, transaction values, or account details.
AI document processing services can combine OCR, layout understanding, language models, and document-specific rules. The best technique depends on the document. Fixed forms may benefit from deterministic extraction, while variable corporate documents may require semantic interpretation. The system should retain the page and location associated with each extracted value so a reviewer can verify it quickly.
Step 4 | Validation Against Rules and Systems
Extraction is only the beginning. document AI validation checks whether a value is plausible, complete, consistent, and aligned with other evidence. Dates can be checked for format and expiry. Addresses can be compared across documents. Names can be normalized before comparison. Ownership percentages can be checked for obvious inconsistencies. Required fields can be verified by customer type and jurisdiction.
Validation should distinguish between formatting corrections and substantive decisions. Standardizing “Street” and “St.” may be a safe transformation; deciding that two different legal names refer to the same person may require stronger evidence or review.
Step 5 | KYC Document Automation
KYC document automation can assemble the extracted and validated information into a structured review package. The workflow can identify which documents are present, which are missing, which values conflict, which documents are expired, and which fields require reviewer confirmation.
The system can also draft requests for missing information. Those messages should refer to the actual gap—such as a missing proof-of-address date or unreadable ownership page—rather than send generic document requests. This improves customer experience and reduces repeated back-and-forth.
Step 6 | Human Review and Exception Queues
Human review is most effective when the AI does the repetitive preparation. Reviewers should see the original document, extracted value, confidence, validation result, and any conflicting evidence in one interface. They should be able to correct the value, approve it, reject the document, or request more information.
Exceptions can be prioritized by risk and uncertainty. A blurry document with one unreadable field may need a different queue than a case containing conflicting ownership information. Queue design is part of the AI product because it determines how uncertainty becomes operational work.
Step 7 | Write-Back to Banking Systems
Approved data can be written to onboarding, CRM, KYC, case-management, or core systems through controlled APIs. The write-back layer should know which fields are safe to update automatically and which require final approval. Sensitive changes should preserve the reviewer identity and source evidence.
AI workflow automation can coordinate the steps around extraction, validation, approval, customer communication, and system updates. The AI should not become an uncontrolled integration layer with broad database access.
Intelligent Document Processing for Banks
intelligent document processing for banks combines several techniques rather than relying on one model. OCR handles image-to-text conversion. Computer vision can detect layout and regions. NLP and language models interpret entities and relationships. Rules validate known constraints. Retrieval can bring in product or jurisdiction requirements. Human reviewers resolve uncertainty.
This layered design is easier to control because each component has a clear job. If extraction quality falls for a new document version, teams can improve that stage without redesigning the entire workflow.
Handling Tables, Statements, and Multi-Page Documents
Bank statements and financial documents often contain tables that span pages, repeated headers, footnotes, currencies, and transaction descriptions. Extraction should preserve row relationships and page context. Where totals matter, deterministic reconciliation can verify that extracted numbers are internally consistent.
Long corporate documents create another challenge: important facts may appear in schedules, appendices, or amendments. A document pipeline can first classify sections, then extract relevant entities and link them back to the exact page. This gives analysts a shorter path to the evidence.
Fraud and Tampering Signals
Document AI can surface signals such as inconsistent fonts, unusual image regions, conflicting metadata, repeated files, suspicious edits, or data mismatches. These signals should be treated as indicators for review rather than proof of fraud. Specialized verification services may still be required for identity authenticity or document forensics.
Generative models should not be asked to make unsupported claims about whether a document is genuine. A better workflow is to combine technical checks, external verification where approved, and analyst review.
Security and Privacy in Document AI
Banking documents contain highly sensitive personal and business information. Access should follow least privilege, with encrypted storage, controlled model endpoints, defined retention, and audit logging. Production documents should not be copied into uncontrolled test environments or personal analyst folders.
AI security guardrails and evaluation can test data leakage, prompt injection, unauthorized retrieval, and unsafe tool use. If a language model receives document text, teams should also understand provider retention and training settings.
Evaluating Document Processing Quality
Accuracy should be measured at multiple levels. Classification accuracy asks whether the document type is correct. Field accuracy measures extracted values. Validation accuracy tests whether conflicts and missing items are identified. Workflow metrics measure reviewer time, rework, processing time, and percentage of cases requiring manual correction.
Not all fields are equally important. A one-character error in a high-risk identifier can matter more than a punctuation difference in an address. Evaluation should weight critical fields and include diverse document quality, languages, layouts, and customer types.
AI evaluation and testing can build a repeatable benchmark with expected documents, fields, edge cases, and exception outcomes so teams can compare model or pipeline changes before release.
A 90-Day Rollout Approach
Weeks 1–2 | Select Documents and Define Ground Truth
Choose a limited set of high-volume document types and create a representative evaluation sample. Define the fields and validations that matter operationally.
Weeks 3–5 | Build Classification and Extraction
Implement intake, classification, extraction, source locations, and confidence scoring. Keep the workflow read-only while quality is measured.
Weeks 6–8 | Add Validation and Reviewer UX
Connect deterministic rules and trusted system data. Build exception queues and reviewer correction flows.
Weeks 9–10 | Integrate Downstream Systems
Add controlled write-back for approved fields and customer requests for missing evidence.
Weeks 11–13 | Pilot, Measure, and Expand
Run the workflow with a limited user group, measure correction rates and handling time, then expand document types only when the baseline is stable.
How to Evaluate AI Document Processing Banking Solutions
Compare vendors and architectures on document coverage, extraction quality, confidence reporting, source traceability, human-review features, API integration, data handling, deployment options, version control, and evaluation support. Ask what happens when a new document layout appears or when the model is uncertain.
A polished demo using clean sample forms does not prove production readiness. Test real scans, cropped images, multi-page files, poor lighting, handwritten additions, conflicting values, and documents from different jurisdictions.
Multilingual and Cross-Jurisdiction Document Processing
Banking onboarding frequently crosses languages and jurisdictions. The same business concept may appear under different labels, date formats, scripts, document structures, and legal terminology. A robust AI document processing banking workflow should preserve the original text while creating normalized fields for downstream systems. Translation may help a reviewer, but the source document remains the evidence.
Evaluation should be segmented by document language and jurisdiction rather than reporting one overall accuracy number. A model that performs well on common English forms may struggle with a smaller set of high-value international documents. Teams should maintain representative test data and route unsupported formats to specialist review.
Entity Resolution Across KYC Documents
One of the hardest problems is deciding whether names, addresses, company identifiers, and ownership entities refer to the same real-world subject. Minor spelling differences may be harmless, while similar-looking names may represent different people. AI document processing banking should therefore separate normalization from identity resolution.
Normalization can standardize case, punctuation, dates, abbreviations, and common address formats. Entity resolution can then combine deterministic identifiers, similarity measures, trusted reference data, and human review. The system should show why records were linked and allow reviewers to reject an incorrect match.
Exact Source Traceability
Every important extracted field should link back to its page or region. This is essential for document AI validation because reviewers need to confirm evidence without searching through the full file. Source traceability also improves incident investigation and model evaluation when a value was extracted incorrectly.
Exception Analytics as a Continuous Improvement Loop
Exception queues contain valuable information about the weaknesses of the process. Track which document types cause the most manual correction, which fields are frequently missing, which issuers produce poor scans, and which validation rules create unnecessary referrals. These patterns can guide model improvements and customer-experience changes.
For example, if many cases fail because customers upload cropped proof-of-address images, the better solution may be improved upload guidance rather than a more complex model. If a specific corporate form repeatedly produces extraction errors, the team can add a specialized parser or targeted training data.
Build Versus Buy for Banking Document AI
Packaged document platforms can accelerate common identity and form processing, while a custom solution may be needed for proprietary onboarding packages, unusual corporate documents, specialized validation, or deep workflow integration. The decision should consider coverage, accuracy, data handling, reviewer experience, API flexibility, evaluation transparency, and total operating cost.
A hybrid approach is common: use specialized services for mature document types and custom extraction for organization-specific files. Enterprise AI development can integrate multiple document capabilities behind a consistent workflow, keeping approval, audit, and data policies under one operating model.
Production Monitoring for AI Document Processing Banking
After launch, monitor volume, processing failures, document mix, field confidence, correction rate, latency, and reviewer workload. A change in upstream scanning, customer behavior, or document templates can shift performance even when the model has not changed. AI document processing banking therefore needs drift detection at the workflow level.
Release management should compare new models or prompts against the existing benchmark before deployment. Critical fields deserve stricter thresholds than low-impact descriptive fields. If quality drops, the system should support rollback or increase manual review until the issue is resolved.
Why Choose AUREXONE AI TECHNOLOGIES for Banking Document AI
AUREXONE designs document processing as an end-to-end operating workflow. The work can include intake, classification, extraction, validation, exception routing, reviewer interfaces, system integration, evaluation, and production monitoring. This avoids the common problem of achieving good OCR while leaving the most expensive manual steps untouched.
Teams can validate a narrow document set with AI proof-of-concept development and then extend the pipeline through AI data engineering as sources and downstream systems grow. For an additional reference when evaluating AUREXONE, see AUREXONE AI TECHNOLOGIES on Google.
Frequently Asked Questions
What is AI document processing banking?
AI document processing banking uses AI to classify banking documents, extract structured information, validate fields, identify missing evidence, and route exceptions during onboarding, KYC, and other document-heavy workflows.
How is intelligent document processing different from OCR?
OCR converts images into text. Intelligent document processing adds classification, semantic extraction, validation, workflow logic, confidence scoring, and human review.
Which banking documents can AI process?
Common candidates include identity documents, proof of address, incorporation records, tax forms, ownership documents, applications, statements, and supporting KYC evidence. Coverage depends on the solution and document variability.
Can AI fully automate KYC decisions?
AI can automate document preparation and many checks, but high-impact policy decisions and uncertain cases may require qualified human review. The appropriate level of automation depends on the institution and use case.
How should extracted fields be verified?
Use format rules, cross-document comparisons, trusted system data, external verification where approved, confidence thresholds, and human review. Preserve the source page or region for evidence.
What happens when a document is unreadable?
The system should flag the issue, identify the affected field or page, and route the case for a new document request or manual review rather than inventing a value.
How do you measure document AI accuracy?
Measure document classification, field-level extraction, critical-field accuracy, validation detection, reviewer correction rate, processing time, and rework. Test across realistic layouts and image quality.
Is banking document AI secure?
It can be designed securely with least-privilege access, encryption, controlled model endpoints, retention policies, audit logs, and testing. Security depends on the entire architecture, not the model alone.
Can document AI write directly into a KYC system?
Yes, but write-back should be controlled. Low-risk validated fields may be automated while sensitive or uncertain updates require reviewer approval and full audit history.
What is a good first document AI pilot?
Choose a few high-volume document types with clear fields and measurable manual effort. Build a ground-truth set, run extraction read-only, measure errors, and add write-back only after quality is demonstrated.
Turn Documents Into Structured, Reviewable Banking Workflows
AI document processing banking creates the most value when the system improves the entire path from incoming file to verified case data. Classification, extraction, validation, human review, and system integration should be designed together. AUREXONE AI TECHNOLOGIES can help banking teams build document workflows that reduce repetitive handling while preserving evidence, control, and reviewer authority.
Если вы хотите быстро и качественно оформить каркасный дом под ключ в спб, обращайтесь к проверенным специалистам.
Строительство каркасного дома занимает гораздо меньше времени, чем кирпичного аналога.
Если вы ищете надежную клинику для эко по омс, в Санкт-Петербурге доступны современные программы помощи в области вспомогательных репродуктивных технологий.
Начинается процесс с комплексного медицинского обследования и обсуждения плана лечения.
Если вам нужно быстро и надежно где сдать спермограмму, обратитесь в наш центр для профессионального обследования.
Результаты обычно готовы через несколько дней.
Если вы хотите продвинуть свой сайт, обязательно изучите опыт лучшие сеошники, чтобы выбрать надежного эксперта.
Выбор эксперта по SEO нередко становится вызовом для бизнесменов.
Планируя встречу или праздник, заранее уточните условия, по которым доступна доставка алкоголя по москве.
Заказ алкоголя с доставкой выручает, если не хочется тратить время на поход в магазин.
Условия оформления и получения следует заранее изучить на сайте сервиса.
Не следует садиться за руль после употребления спиртного.
За разъяснениями по заказу покупатель может обратиться к поддержке.
Обзор Workspace поможет разобраться, кто входит в число лучшие сеошники России.
Одним компаниям важно увеличить поток заявок, другим — укрепить позиции сайта по ключевым запросам.
Аналитические способности и внимание к деталям имеют не меньшее значение.
Заранее выясните, каким образом будет строиться работа после заключения договора.
Благодаря взвешенному выбору продвижение становится системным и прозрачным процессом.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы seo и выберите подходящую программу.
Рейтинг курсов SEO
Важны продолжительность обучения, формат обратной связи и доступ к материалам после окончания курса.
Полезнее всего отзывы с конкретными примерами достигнутых результатов и возникших проблем.
Практические задания помогают научиться анализировать соперников и следить за позициями ресурса.
Для старта подойдут программы, где материал объясняют поэтапно и поддерживают наставники.
Обзор Workspace поможет разобраться, кто входит в число лучшие seo специалисты России.
Далее специалист находит ошибки сайта, изучает структуру разделов и проверяет полезность материалов для целевой аудитории.
Профессионал регулярно анализирует посещаемость, поисковую видимость и поведение аудитории.
Ответственный специалист определяет приоритеты вместе с заказчиком, регулярно готовит отчётность и сообщает о рисках.
Наиболее подходящий специалист не всегда оказывается самым известным или дорогим.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы seo и выберите подходящую программу.
Рейтинг курсов SEO
Рейтинг пригодится как начинающим, так и тем, кто хочет обновить знания в области SEO.
Оценивать стоит актуальность содержания, опыт преподавателей и объём самостоятельной работы.
Качественный курс обучает основам технической оптимизации веб-сайтов.
Перед оплатой стоит изучить учебный план и уточнить, кому адресовано обучение.
Обзор Workspace поможет разобраться, кто входит в число лучшие seo специалисты России.
Далее специалист находит ошибки сайта, изучает структуру разделов и проверяет полезность материалов для целевой аудитории.
Специалист регулярно проверяет изменения трафика, видимость страниц и поведение посетителей.
До начала сотрудничества обсудите формат дальнейшей совместной работы.
Оценивайте опыт специалиста в своей сфере, качество общения и умение соотносить SEO-задачи с целями компании.
Уточните условия и часы работы сервиса: доставка алкоголя круглосуточно в москве.
Такой способ экономит время, но требует соблюдения законодательства.
При заказе указывают адрес, контактный телефон и удобное время получения.
Покупателю стоит заранее удостовериться, что продавец соблюдает правила и сообщает достоверные данные.
Если товар поврежден или состав заказа отличается от указанного, немедленно уведомите продавца.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы seo и выберите подходящую программу.
Обзор лучших курсов по SEO
Важны продолжительность обучения, формат обратной связи и доступ к материалам после окончания курса.
Лучше искать подробные мнения с описанием результатов и сложностей.
Участники разбираются, как собирать поисковые запросы и распределять их по страницам.
Новичкам лучше выбирать курсы с понятной структурой и помощью преподавателя.
Планируя встречу или праздник, заранее уточните условия, по которым доступна доставка алкоголя на дом москва.
Сравнить объём и особенности напитков можно по описанию товаров.
Покупателю стоит заранее проверить условия оформления и получения заказа.
При выборе напитков важно учитывать собственный вкус и формат мероприятия.
Перед оплатой стоит проверить итоговую стоимость и условия доставки.
Обзор Workspace поможет разобраться, кто входит в число лучшие seo специалисты России.
Вначале квалифицированный эксперт анализирует сайт, конкурентов и специфику рынка.
Аналитические способности и внимание к деталям имеют не меньшее значение.
Подробный разбор кейса информативнее общих заявлений о многолетнем опыте.
Для устойчивого результата бизнесу важно своевременно предоставлять доступы, материалы и обратную связь.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы seo и выберите подходящую программу.
Как выбрать курс по поисковому продвижению
В основу оценки входят учебный план, компетенции экспертов и практическая ценность курса.
К таким показателям относятся современность учебного плана, квалификация экспертов и практические задания.
Практические задания помогают научиться анализировать соперников и следить за позициями ресурса.
Для старта подойдут программы, где материал объясняют поэтапно и поддерживают наставники.
Уточните условия и часы работы сервиса: доставка алкоголя москва алкоторг.
Сначала рекомендуется ознакомиться с выбором напитков, ценами и данными продавца.
В некоторых случаях покупателю доступна предварительная оплата, а в других расчет проводится при получении.
Доступность доставки определяется местными условиями и действующими правилами.
Чтобы упростить решение возможного спора, сохраните документы или электронное подтверждение заказа.
Обзор Workspace поможет разобраться, кто входит в число лучшие seo специалисты России.
Опытный специалист сначала изучает сайт, конкурентов и особенности ниши.
Аналитические способности и внимание к деталям имеют не меньшее значение.
Профессиональный SEO-подрядчик согласовывает первоочередные задачи, систематически отчитывается и заранее обозначает возможные проблемы.
Ориентируйтесь на его опыт в вашей нише, ясность коммуникации и способность связывать задачи с целями бизнеса.
Планируя встречу или праздник, заранее уточните условия, по которым доступна доставка алкоголя тушино.
Нужные напитки можно найти в онлайн-каталоге и добавить в заказ.
Правила продажи и доставки алкогольной продукции устанавливаются законом.
При противопоказаниях или сомнениях разумнее не употреблять спиртное.
Подробности о возможных доплатах стоит искать в условиях доставки.
Уточните условия и часы работы сервиса: доставка алкоголя по москве.
Такой способ экономит время, но требует соблюдения законодательства.
Продавец может предложить оплату до доставки или расчет после передачи покупки.
Перед покупкой следует убедиться, что продавец работает законно и предоставляет достоверные сведения.
Алкоголь следует употреблять умеренно и только совершеннолетним.
Обзор Workspace поможет разобраться, кто входит в число лучшие сео специалисты России.
Подбор специалиста по SEO стоит начинать с постановки бизнес-целей.
Они не гарантируют быстрых позиций в топе, потому что знают: SEO требует времени и системной работы.
Во время поиска подрядчика стоит ознакомиться с его проектами и узнать, какую работу он выполнял.
Устойчивое продвижение требует своевременной передачи доступов, информации и обратной связи со стороны бизнеса.
Планируя встречу или праздник, заранее уточните условия, по которым доступна алкоголь с доставкой мск.
Покупатель выбирает напитки в каталоге и оформляет заказ онлайн.
Покупателю стоит следить за сообщениями службы доставки и отвечать на звонки.
Важно помнить, что спиртные напитки несут риски для здоровья.
Внимательное оформление и соблюдение правил делают получение покупки понятнее.
Уточните условия и часы работы сервиса: доставка алкоголя ночью в москве на дом.
Перед заказом стоит проверить ассортимент, цены и сведения о продавце.
Перед подтверждением заявки стоит убедиться, что корзина и итоговая цена указаны верно.
При отсутствии подтверждения совершеннолетия продавец имеет право отказать в выдаче покупки.
При передаче заказа проверьте упаковку, количество товаров и соответствие покупки чеку.
Обзор Workspace поможет разобраться, кто входит в число лучшие сео специалисты России.
Опытный специалист сначала изучает сайт, конкурентов и особенности ниши.
Эти данные помогают специалисту корректировать стратегию и обосновывать ключевые решения.
Уточните, какие меры применялись, какие трудности возникли у команды и каким способом оценивалась эффективность.
Благодаря взвешенному выбору продвижение становится системным и прозрачным процессом.
Планируя встречу или праздник, заранее уточните условия, по которым доступна доставка алкоголя москва 24.
Сравнить объём и особенности напитков можно по описанию товаров.
Покупателю стоит следить за сообщениями службы доставки и отвечать на звонки.
Употребление алкоголя может быть опасно для здоровья.
Некоторые сервисы устанавливают минимальную сумму заказа или дополнительные сборы.
Уточните условия и часы работы сервиса: доставка сигарет и алкоголя на дом москва.
Доставка алкоголя позволяет заказать напитки онлайн и получить их по указанному адресу.
Перед подтверждением заявки стоит убедиться, что корзина и итоговая цена указаны верно.
Условия доставки зависят от региона и действующих ограничений.
Ответственный подход начинается с внимательного выбора продавца и заканчивается безопасным обращением с покупкой.
Обзор Workspace поможет разобраться, кто входит в число рейтинг seo специалистов России.
После этого он выявляет технические проблемы, оценивает устройство страниц и выясняет, отвечает ли контент запросам аудитории.
Вместо громких гарантий эксперт предлагает понятные этапы, сроки и показатели для оценки прогресса.
Конкретный анализ проекта говорит больше, чем расплывчатые слова о большом стаже.
Благодаря сотрудничеству сторон проще своевременно выявлять перемены и выбирать аргументированные решения.
Планируя встречу или праздник, заранее уточните условия, по которым доступна доставка алкоголя по москве.
Когда товара нет на складе, его можно заменить похожей позицией.
Выбрать подходящее время можно среди интервалов, предложенных при заказе.
Если человек выпил, ему не стоит садиться за руль.
Точная проверка данных и следование правилам помогают избежать недоразумений.
Уточните условия и часы работы сервиса: купить алкоголь ночью.
Лучше до оформления уточнить, какие документы потребуются для получения покупки.
Способ расчета зависит от продавца: иногда заказ оплачивают заранее, иногда — при получении.
Возрастные ограничения помогают защищать потребителей и выполнять требования закона.
Не стоит садиться за руль после употребления спиртных напитков или предлагать их тем, кому они противопоказаны.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы seo и выберите подходящую программу.
Рейтинг курсов SEO
Он учитывает содержание занятий, квалификацию преподавателей и практическую пользу.
Мнения бывших студентов дают представление о курсе, однако их нужно анализировать внимательно.
Во время занятий слушатели учатся выявлять технические проблемы, работать со структурой сайта и оценивать его скорость.
Выбирайте программу с учётом личных целей, доступного времени и бюджета.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы сео и выберите подходящую программу.
Рейтинг курсов SEO
Выбирая обучение, не следует ограничиваться сравнением стоимости.
Мнения бывших студентов дают представление о курсе, однако их нужно анализировать внимательно.
Такие знания помогают подготовиться к дальнейшему продвижению ресурса.
Тем, у кого уже есть опыт, подойдут углублённые программы по SEO-аналитике и техническому продвижению.
Планируя встречу или праздник, заранее уточните условия, по которым доступна алкоголь ночью.
Если нужной позиции нет в наличии, можно рассмотреть похожий вариант.
Получить алкоголь вправе совершеннолетний человек, предъявив документ для подтверждения возраста.
Важно помнить, что спиртные напитки несут риски для здоровья.
Внимательное оформление и соблюдение правил делают получение покупки понятнее.
Обзор Workspace поможет разобраться, кто входит в число рейтинг сео специалистов России.
Далее специалист находит ошибки сайта, изучает структуру разделов и проверяет полезность материалов для целевой аудитории.
Вместо громких гарантий эксперт предлагает понятные этапы, сроки и показатели для оценки прогресса.
Конкретный анализ проекта говорит больше, чем расплывчатые слова о большом стаже.
Лучший эксперт для конкретной компании — не обязательно самый дорогой или известный.
Если вы планируете освоить поисковую оптимизацию, изучите рейтинг курсов сео и выберите подходящую программу.
Рейтинг курсов SEO
Он учитывает содержание занятий, квалификацию преподавателей и практическую пользу.
Расплывчатые гарантии быстрого результата не могут заменить подробного описания учебного плана.
Участники разбираются, как собирать поисковые запросы и распределять их по страницам.
До покупки курса важно проверить программу и понять, для какого уровня она предназначена.
Планируя встречу или праздник, заранее уточните условия, по которым доступна купить алкоголь 24.
Если нужной позиции нет в наличии, можно рассмотреть похожий вариант.
Выбрать подходящее время можно среди интервалов, предложенных при заказе.
Продуманный заказ помогает подойти к покупке ответственнее.
Покупателю важно заранее увидеть общую сумму покупки вместе с доставкой.
Обзор Workspace поможет разобраться, кто входит в число лучшие сеошники России.
Такой подход помогает сформировать план работ, а не ограничиваться случайным набором рекомендаций.
Профессиональные специалисты по SEO понятно объясняют даже непростые рабочие задачи.
Подробный разбор кейса информативнее общих заявлений о многолетнем опыте.
Благодаря взвешенному выбору продвижение становится системным и прозрачным процессом.
Если вы планируете освоить поисковую оптимизацию, изучите рейтинг курсов seo и выберите подходящую программу.
Как выбрать курс по поисковому продвижению
Рейтинг пригодится как начинающим, так и тем, кто хочет обновить знания в области SEO.
Для объективного сравнения SEO-курсов используют ряд критериев.
Кроме того, студенты тренируются изучать конкурентов и наблюдать за динамикой поисковых позиций.
Тем, у кого уже есть опыт, подойдут углублённые программы по SEO-аналитике и техническому продвижению.
Планируя встречу или праздник, заранее уточните условия, по которым доступна заказать алкоголь ночью.
Нужные напитки можно найти в онлайн-каталоге и добавить в заказ.
Сервис обычно сообщает доступные интервалы при оформлении покупки.
При противопоказаниях или сомнениях разумнее не употреблять спиртное.
Покупателю важно заранее увидеть общую сумму покупки вместе с доставкой.
Обзор Workspace поможет разобраться, кто входит в число рейтинг сео специалистов России.
Вначале квалифицированный эксперт анализирует сайт, конкурентов и специфику рынка.
Опираясь на показатели, он обновляет план продвижения и объясняет важные изменения.
До начала сотрудничества обсудите формат дальнейшей совместной работы.
Наиболее подходящий специалист не всегда оказывается самым известным или дорогим.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы сео и выберите подходящую программу.
Как выбрать курс по поисковому продвижению
Важны продолжительность обучения, формат обратной связи и доступ к материалам после окончания курса.
Плюсом будут индивидуальные советы и подробный разбор выполненных заданий.
На практике они также учатся оценивать конкурентов и отслеживать изменения позиций сайта.
Взвешенный выбор поможет превратить обучение в полезную инвестицию в профессиональное развитие.
Планируя встречу или праздник, заранее уточните условия, по которым доступна круглосуточная доставка алкоголя москва.
При отсутствии выбранного напитка стоит посмотреть доступные аналоги.
Перед заказом важно ознакомиться с правилами доставки и выдачи товаров.
Подходящий напиток выбирают, ориентируясь на предпочтения и ситуацию.
Внимательное оформление и соблюдение правил делают получение покупки понятнее.
Обзор Workspace поможет разобраться, кто входит в число лучшие сео специалисты России.
Затем он определяет технические ошибки, анализирует структуру страниц и проверяет, соответствует ли контент потребностям аудитории.
Они не гарантируют быстрых позиций в топе, потому что знают: SEO требует времени и системной работы.
Подробный разбор кейса информативнее общих заявлений о многолетнем опыте.
При выборе учитывайте знание вашей ниши, понятность коммуникации и связь предлагаемых действий с бизнес-целями.
Если вы планируете освоить поисковую оптимизацию, изучите лучшие курсы сео и выберите подходящую программу.
Обзор лучших курсов по SEO
Полезно также проверить, предусмотрены ли практические задания на реальных проектах.
Дополнительным преимуществом становятся разборы работ и персональные рекомендации.
Слушатели осваивают сбор запросов и их грамотное распределение по структуре сайта.
Опытным специалистам полезнее углублённые курсы по аналитике, стратегии и техническому SEO.
алкоголь доставка москва 24
Доставка алкоголя становится все более популярной среди покупателей .
Современные службы доставки позволяют заказать алкоголь и получить его в кратчайшие сроки.
Одна из главных особенностей – разнообразие предложений и простота оформления заказа.
Ключевым фактором является рейтинг и надежность сервиса.
В большинстве случаев достаточно выбрать нужный напиток, указать адрес и оплатить.
Удобно, что есть возможность получить профессиональную помощь при выборе.
В каталоге представлены различные категории напитков для любого вкуса .
В большинстве случаев доставка включена в цену или предоставляется за отдельную плату.
Недорогие варианты подходят для ежедневных покупок, а более премиальные — для особых случаев .
Доставка осуществляется в оговоренные сроки, часто в течение нескольких часов после заказа .
Некоторые компании предлагают круглосуточную поддержку и возможность заказа в любое время .
Сотрудники аккуратно упаковывают напитки, чтобы избежать повреждений .
Важное условие — соблюдение законодательства при доставке алкоголя .
Безопасность доставки гарантирована использованием проверенных курьеров и надежных упаковок .
Доставка алкоголя — это современное решение, которое позволяет экономить время и избегать походов в магазины .
служба доставки алкоголя москва
Доставка алкоголя становится все более популярной среди покупателей .
Современные службы доставки позволяют заказать алкоголь и получить его в кратчайшие сроки.
Особенности доставки включают широкий ассортимент и возможность выбора наиболее подходящего варианта .
Раздел 1: Выбор сервиса и оформление заказа.
Процесс оформления прост и понятен, что позволяет сэкономить время .
Удобно, что есть возможность получить профессиональную помощь при выборе.
В каталоге представлены различные категории напитков для любого вкуса .
Цены варьируются в зависимости от класса продукции и выбранного бренда .
Недорогие варианты подходят для ежедневных покупок, а более премиальные — для особых случаев .
В большинстве случаев доставка возможна в тот же день.
В случае срочной необходимости много сервисов обеспечивают экспресс-доставку .
Сотрудники аккуратно упаковывают напитки, чтобы избежать повреждений .
В некоторых регионах предоставление алкоголя лицам без подтвержденного возраста запрещено.
Безопасность доставки гарантирована использованием проверенных курьеров и надежных упаковок .
Доставка алкоголя — это современное решение, которое позволяет экономить время и избегать походов в магазины .
доставка алкоголя на дом
Услуга доставки алкоголя набирает популярность у потребителей.
Современные службы доставки позволяют заказать алкоголь и получить его в кратчайшие сроки.
Одна из главных особенностей – разнообразие предложений и простота оформления заказа.
Раздел 1: Выбор сервиса и оформление заказа.
Процесс оформления прост и понятен, что позволяет сэкономить время .
Также многие ресурсы предлагают дополнительные услуги, такие как консультации и рекомендации .
Ассортимент обычно включает все популярные виды алкоголя: вино, пиво, крепкие напитки и ликеры .
На стоимость влияет качество, объем и эксклюзивность напитка .
Справедливая ценовая политика делает услугу доступной широкому кругу покупателей.
Раздел 3: Условия и сроки доставки.
Заказ с доставкой возможен как в будние, так и в выходные дни.
Сотрудники аккуратно упаковывают напитки, чтобы избежать повреждений .
Компания обязана проверять возраст получателя и осуществлять контроль .
Безопасность доставки гарантирована использованием проверенных курьеров и надежных упаковок .
Эта услуга становится всё более востребованной благодаря удобству и скорости .
алкоголь купить круглосуточно с доставкой
Услуга доставки алкоголя набирает популярность у потребителей.
Сегодня существует множество сервисов, обеспечивающих быструю доставку алкоголя на дом .
Основными преимуществами являются широкий выбор напитков и удобство заказа .
Раздел 1: Выбор сервиса и оформление заказа.
Процесс оформления прост и понятен, что позволяет сэкономить время .
Также многие ресурсы предлагают дополнительные услуги, такие как консультации и рекомендации .
Покупатели могут выбрать из широкого спектра брендов и видов алкоголя.
Цены варьируются в зависимости от класса продукции и выбранного бренда .
Недорогие варианты подходят для ежедневных покупок, а более премиальные — для особых случаев .
В большинстве случаев доставка возможна в тот же день.
Некоторые компании предлагают круглосуточную поддержку и возможность заказа в любое время .
Доставка осуществляется аккуратно, с соблюдением всех правил хранения и транспортировки .
Важное условие — соблюдение законодательства при доставке алкоголя .
Для клиента важно убедиться в надежности выбранной службы.
Доставка алкоголя — это современное решение, которое позволяет экономить время и избегать походов в магазины .